When an n8n SEO workflow hits an API rate limit, reduce request pressure according to that provider's documented quota and retry only within a bounded policy. Inspect the actual response first. Adding retries without controlling batch size, concurrent runs and completed work can turn a temporary limit into a larger queue of repeated requests.
This guide is for an authorized workflow owner processing SEO data. It offers a request-budget worksheet and a testable design, not a way to bypass a service's limits. No production API was load-tested for this article.
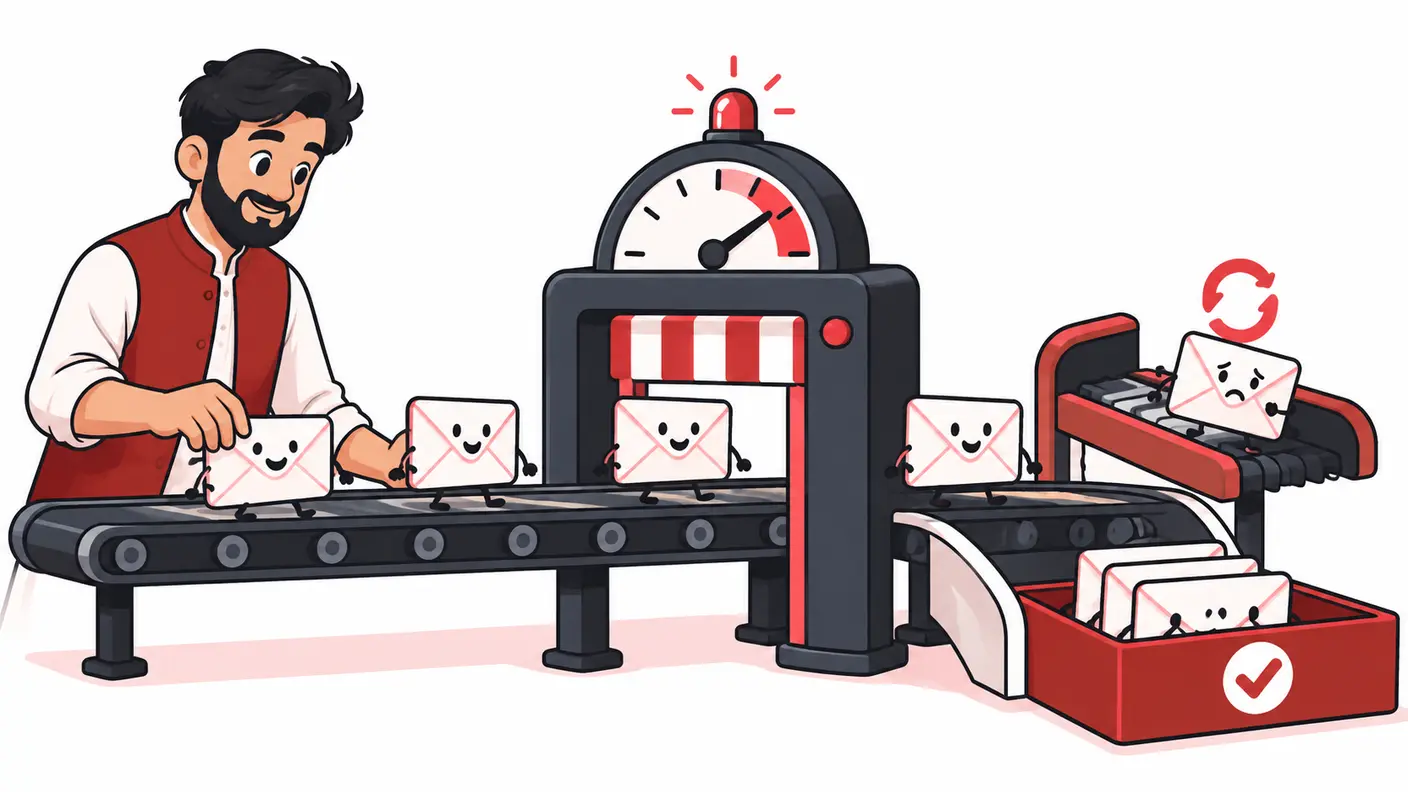
Identify the limit before changing the workflow
Record which service, endpoint and credential scope is affected. A workflow can contain several APIs with different constraints. A request-per-minute limit, daily allowance, concurrent-job ceiling and payload-size limit require different responses.
Read the service's current API documentation and the actual error details. Do not assume every failure is a rate limit merely because a workflow processes many items. Authentication, malformed input and unsupported operations need their own diagnosis.
For the broader selection of tasks to automate, see the SEO automation workflow guide. Here the narrow objective is to finish authorized requests reliably within an explicit capacity budget.
What current official documentation supports
n8n's rate-limit documentation, reviewed October 18, 2026, describes Retry On Fail, Loop Over Items with Wait, and HTTP Request batching as relevant mechanisms. Retry settings live in the node's Settings; looping and waiting can pace smaller groups of work. Check the current node and provider documentation rather than assuming one generic setting fits every quota.
RFC 6585 defines HTTP 429 as too many requests in a period and permits a Retry-After header. It does not specify one universal counting method. Treat the provider's documented scope and response information as part of the retry decision.
The arithmetic, state model and test matrix below are an editorial design framework. They are not a ready-to-import n8n export or a claim that a particular provider supports these illustrative limits.
Step 1: map the real request fan-out
Count remote calls, not just input rows. A single client may require several endpoints, pagination requests and follow-up status checks. An apparently small spreadsheet can therefore create much more traffic than its row count suggests.
List each operation in the workflow and estimate its calls per item. Include branches that make additional requests and other workflows using the same account or credential. Then compare the combined demand with the relevant quota.
| Budget field | What to record |
|---|---|
| Provider and endpoint | Which documented limit applies |
| Quota scope | Account, project, credential, endpoint or another defined boundary |
| Calls per item | Base requests plus pagination and status checks |
| Other consumers | Scheduled runs and tools sharing the same allowance |
| Peak concurrency | How many request-producing executions can overlap |
| Retry budget | Extra attempts allowed before the item is deferred |
| Completion window | When the report or job is actually needed |
This worksheet often identifies the cause before any node setting changes. If several independent workflows share one allowance, slowing only one branch may not control the total.
Step 2: calculate a conservative starting pace
Consider an illustrative API allowing thirty requests per minute across a shared account. One serial request every three seconds produces approximately twenty requests per minute before processing overhead. That leaves some room, but it is not a guarantee if other consumers use the same account.
If three workflows each run that pattern independently, their combined theoretical pace is about sixty requests per minute. A local delay in every workflow does not create a shared account-wide limiter.
For an initial estimate, divide the chosen interval by the planned number of requests, then reduce the pace to allow for other consumers and retries. Validate against the provider's actual counting window, concurrency rules and daily limits. The arithmetic is a planning aid, not a substitute for those rules.
Step 3: separate pacing from retries
Pacing controls ordinary request pressure before an error occurs. Retrying handles an eligible failed attempt afterward. Design both explicitly; they are not interchangeable.
For a simple read-only batch, evaluate the documented Loop Over Items and Wait pattern: take a small group, call the service, record the result, pause and return for the next group. Keep the final output path separate from the continuing loop.
Alternatively, assess the HTTP Request node's supported batching settings for that operation. Check what a batch means in the node and what the remote API accepts. Grouping input items is not proof that the provider offers a bulk endpoint or charges only one request.
Use Retry On Fail only with an intentional attempt count and delay suitable for the operation. Do not assume that enabling it automatically implements provider-aware exponential backoff, a global shared limiter or safe write reconciliation.
Step 4: define a bounded 429 policy
Write the policy before enabling automatic recovery. State which responses are eligible, how any provider wait instruction is handled, the fallback delay when no usable instruction is available, maximum attempts and the point at which the item is deferred.
A conceptual sequence is:
Send the authorized request.
If successful, validate and record completion.
If rate-limited, record the response and attempt count.
If the retry budget is exhausted, defer the item and notify its owner.
Otherwise wait according to the approved provider-aware policy.
Retry the unresolved operation, not the entire completed batch.
This is design pseudocode, not executable n8n configuration. A developer must map it to the installed nodes, available response fields and durable state. Do not assume a header is accessible without checking the chosen integration's output.
If using progressively longer fallback waits, define a cap and an overall deadline. A long-running job that retries indefinitely may miss the business deadline while giving the appearance that recovery is underway.
Step 5: treat writes differently from reads
Fetching a report and creating a WordPress post have different consequences when the response is uncertain. Before retrying a write, establish whether it may already have succeeded. Use the destination's supported idempotency or reconciliation design where available.
This guide does not implement publishing duplicate prevention. It establishes the boundary: a delay is not proof that repeating a create operation is safe. Keep the retry policy connected to the actual operation, not just the error code.
For completed read-only items, store enough state to avoid unnecessarily fetching them again when a later item is deferred. Include the item key, operation, result status and last attempt time without storing secrets in general logs.
Step 6: define completeness before producing a report
A workflow that returns data for nine of ten clients has not completed the same task as one that returns all ten. Decide whether partial output is permitted, how missing items are labelled and who receives the follow-up task.
Do not replace a rate-limited response with zero traffic or an empty success object. That converts an operational gap into misleading business evidence. Preserve “not retrieved” as a distinct state.
If a client report may use partial data, include the actual coverage and limitation. If complete coverage is mandatory, stop the final delivery step until the requirement is met or an authorized owner accepts a clearly described exception.
Worked example: a weekly multi-client SEO report
Imagine a Lahore agency retrieves three paginated report sections for each of twelve clients. The initial workflow launches many requests together and encounters rate limits. These numbers are illustrative, not measurements from an API test.
The owner maps request fan-out, including pagination and another workflow using the same credential. They choose a controlled pace, stagger overlapping work and define a retry budget for unresolved reads. Completed client sections are recorded separately.
One item still cannot finish within the reporting window. The workflow marks that section as not retrieved and routes it to the responsible owner rather than inserting a zero. The final delivery follows the agreed completeness rule.
The improvement is a traceable request budget and honest output state. The agency does not claim that a generic delay eliminated every rate-limit error or that a report finishing once proves long-term reliability.
Test the design without stressing production
| Test case | Expected behavior |
|---|---|
| Successful request | Validated result recorded once |
| Controlled rate-limit response | Eligible bounded wait and retry path |
| No usable wait instruction | Documented fallback, not an uncontrolled immediate retry |
| Retry budget exhausted | Deferred item and accountable follow-up |
| Overlapping runs | Combined pressure reviewed against shared scope |
| Uncertain write result | Reconciliation before another create attempt |
| Partial retrieval | Missing data remains distinct from a genuine zero |
Use controlled test responses or an approved low-volume environment where possible. Do not deliberately overwhelm a third-party API to prove that it enforces limits.
Verify units carefully. A delay field in milliseconds and a planning note in seconds can produce a large configuration error. Record the actual saved value and observe the test execution's timing.
Common mistakes and troubleshooting
Every retry immediately hits another limit
Review the wait policy, shared consumers and concurrent executions. Retrying faster does not solve an account-wide pressure problem.
A daily allowance is exhausted
Respect the documented reset and business deadline. A per-second delay cannot create additional daily quota. Defer work or obtain an authorized capacity change rather than rotating identities to evade limits.
The loop repeats completed items
Inspect state and item routing. Distinguish the current unresolved request from work already validated and stored.
One large request fails despite low frequency
Review payload and response limits as well as request rate. Smaller valid requests or supported pagination may be the relevant design change.
The workflow finishes but the report is incomplete
Add an explicit coverage check before delivery. A technically successful execution and a complete business deliverable are different criteria.
Frequently asked questions
Should I enable retries on every node?
No. Evaluate the operation, failure type and consequences. Automatic retries on an uncertain write can be materially different from repeating a read.
Is one second between requests always safe?
No. The correct pace depends on the provider's limits, shared scope, concurrency and other usage. Avoid universal delay recipes.
Can I use more credentials to avoid the restriction?
Do not design around evading a provider's controls. Use authorized capacity, an appropriate schedule and a documented request budget.
Does an alert prove the workflow recovered?
No. Recovery requires verified results and completeness, not merely a received notification or a retry attempt.
Conclusion
Map real request demand, respect the provider's scope and pace ordinary work before adding bounded retries. Preserve completed state and distinguish missing data from zero. A dependable SEO workflow knows when to continue, when to defer and what evidence is required before reporting success.
Need help applying this?
Get a practical review focused on the issue, evidence and next actions.
Contact Shahzaib