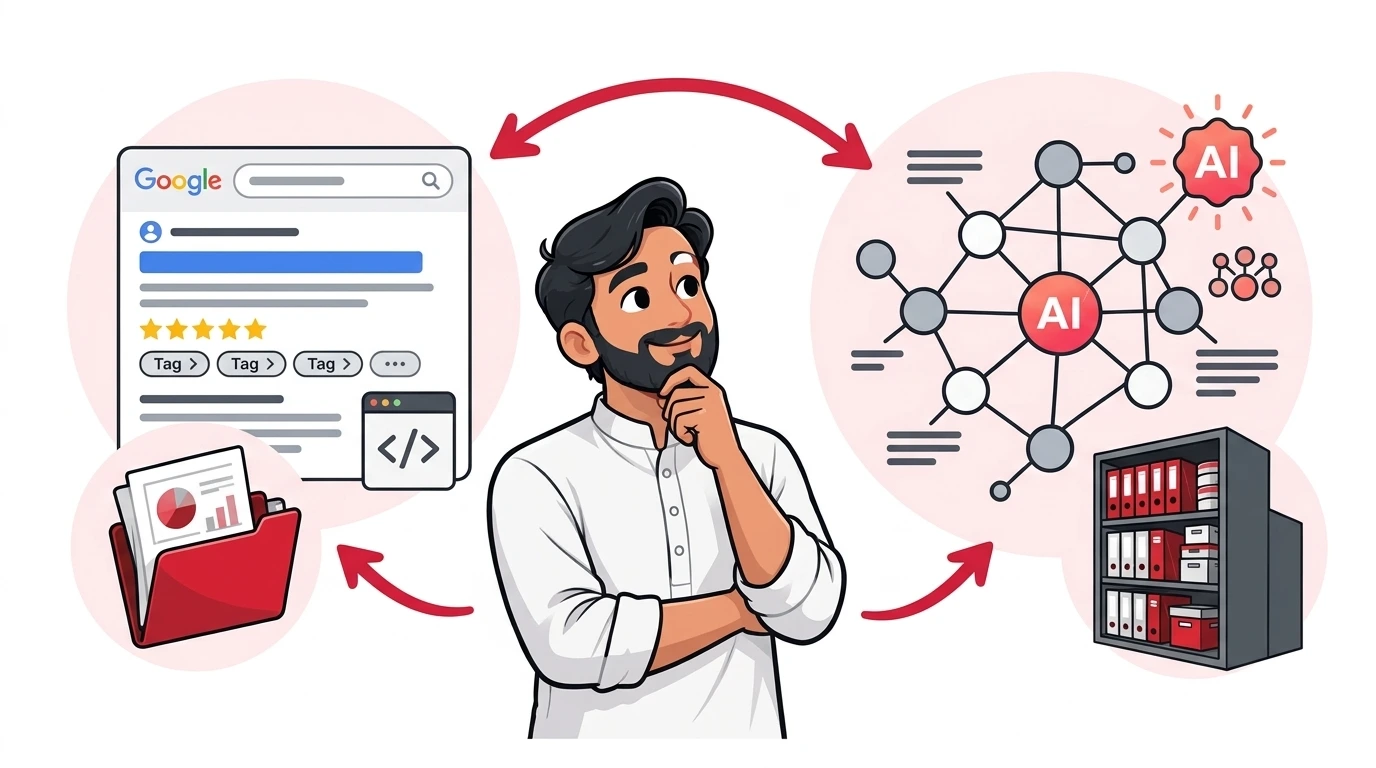
Understanding the difference between seo schema and geo schema is essential in 2027 as search evolves from traditional Google rich snippets into generative AI answer engines like Perplexity, ChatGPT, and Claude. While both rely on JSON-LD syntax, their underlying architectural objectives, target parsers, and entity models are fundamentally distinct.
Traditional SEO schema was designed for search engine web crawlers (like Googlebot) to parse structured attributes—as explored in our schema markup for AI search engines guide—for enhanced SERP displays such as review stars, FAQ accordions, and breadcrumbs. In contrast, GEO schema (Generative Engine Optimization schema) is engineered for Retrieval-Augmented Generation (RAG) pipelines and Large Language Model (LLM) entity graphs. GEO schema establishes machine-readable factual consensus, claims verification, and entity disambiguation that AI models require before citing a brand in generative answers.
Comparison Matrix: SEO Schema vs. GEO Schema
Here is how traditional search schema compares against generative engine schema across critical operational vectors:
| Architecture Vector | Traditional SEO Schema | Generative Engine (GEO) Schema |
|---|---|---|
| Primary Target Parser | Googlebot & Bingbot search indexers | LLM RAG scrapers (SearchGPT, Perplexity, Claude, Gemini) |
| Core Strategic Goal | SERP real estate & click-through rate (CTR) | Entity disambiguation & AI answer citation frequency |
| Primary Schema.org Types | Article, FAQPage, Product, Review |
AboutPage, ItemPage with nested about, mentions, and knowsAbout |
| Entity Resolution | Isolated URL-level properties | Global Knowledge Graph reconciliation via sameAs (Wikidata, Crunchbase) |
| Fact & Claim Validation | Rarely verified against external graphs | Directly binds statistical claims to verifiable source entities |
| Vulnerability to Penalties | FAQ spam penalties & hidden text manual actions | Hallucination penalties & exclusion from LLM training retrieval sets |
What Traditional SEO Schema Achieves
Traditional SEO schema was standardized around the 2011 Schema.org initiative. Its primary purpose is visual presentation in search engine result pages (SERPs):
- Rich Snippets: Displaying aggregate review stars, recipe cook times, or event dates directly beneath a blue link.
- SERP Accordions: Expanding search result footprints through
FAQPagemarkup (though heavily restricted by Google in recent updates). - Site Navigation: Providing breadcrumb hierarchy and sitelinks search box navigation.
What GEO Schema Achieves in 2027
When an LLM processes an enterprise query—such as "What are the best enterprise SEO platforms for healthcare?"—it does not parse web pages to display stars. Instead, it extracts semantic triples: [Subject] -> [Predicate] -> [Object]. If you are tracking these citation triggers across AI search engines, deploying dedicated best ChatGPT SEO rank tracking software becomes indispensable.
GEO schema bridges this gap by explicitly mapping your page content into the LLM's multi-dimensional vector space:
- Entity Reconciliation (
sameAs): Links your company, founders, and core products directly to authoritative third-party entities like Wikidata, DBpedia, and regulatory registries. - Disambiguation (
about&mentions): Explicitly instructs the AI model which industry entities are being discussed, preventing catastrophic hallucinations. - Topical Authority (
knowsAbout): Quantifies the author and organizational credentials in specific scientific, financial, or technical domains.
Code Comparison: Traditional SEO vs. GEO Schema
Below is an example comparing a basic Article SEO schema against a modern, citation-ready GEO entity schema:
1. Traditional Basic SEO Schema (Surface-Level Only)
{
  "@context": "https://schema.org",
  "@type": "Article",
  "headline": "How Cloudflare Edge Workers Accelerate SEO",
  "author": {
    "@type": "Person",
    "name": "Shahzaib Ul Hassan"
  },
  "publisher": {
    "@type": "Organization",
    "name": "ShazzSEO"
  }
}
2. Modern GEO Schema with Entity Disambiguation
{
  "@context": "https://schema.org",
  "@type": "TechArticle",
  "headline": "How Cloudflare Edge Workers Accelerate SEO",
  "about": [
    {
      "@type": "SoftwareApplication",
      "name": "Cloudflare Workers",
      "sameAs": "https://www.wikidata.org/wiki/Q110971842"
    }
  ],
  "mentions": [
    {
      "@type": "Thing",
      "name": "Content Delivery Network",
      "sameAs": "https://en.wikipedia.org/wiki/Content_delivery_network"
    }
  ],
  "author": {
    "@type": "Person",
    "name": "Shahzaib Ul Hassan",
    "url": "https://shazzseo.com/about-me/",
    "sameAs": [
      "https://www.linkedin.com/in/shahzaib-ul-hassan-44681410a/",
      "https://x.com/shazzseo"
    ],
    "knowsAbout": [
      "Technical SEO",
      "Generative Engine Optimization",
      "Edge Computing"
    ]
  }
}
Implementation Checklist for GEO Schema
- Audit Your Existing Entities: Map all company products, leadership, and concepts to corresponding Wikidata or Wikipedia IDs.
- Enrich
aboutandmentionsArrays: Explicitly tag every primary concept with its canonical Knowledge Graph URI. - Bind Numerical Claims: Use schema to explicitly state verified benchmarks or performance numbers directly in JSON-LD.
- Validate Syntax and RAG Parsing: Test schemas against Google's Rich Results Test and validate structured retrieval using Claude SEO auditing tools.
For custom engineering and site-wide implementation, explore our dedicated technical schema markup services.
Conclusion
Traditional SEO schema remains necessary for Google SERP features, but GEO schema is mandatory for winning citations across LLMs and answer engines. Implementing both ensures complete coverage across traditional crawlers and modern conversational search agents.